cogvideox — text and image to video
Explore the model guide and quick start.
Browse sample scenes or review project resources.
Project Updates
- 🔥🔥 News:
2025/03/24— CogKit brings fine-tuning and inference tools together for the CogView4 and CogVideoX model families. - 🔥 News:
2025/02/28— DDIM Inverse support was added for CogVideoX-5B and CogVideoX1.5-5B. - 🔥 News:
2025/01/08— The Diffusers-based LoRA fine-tuning code was updated with lower-memory workflows. - 🔥 News:
2024/11/15— CogVideoX1.5 became available in a Diffusers version, with only small changes needed to previous code. - 🔥 News:
2024/11/08— CogVideoX1.5 extended the series with higher-resolution, ten-second generation and image-to-video support at varying resolutions. - 🔥 News:
2024/10/13— A single-GPU fine-tuning framework for CogVideoX-5B was released with support for multiple resolutions. - 🔥 News:
2024/10/10— The technical report was updated with further training details and demonstrations. - 🔥 News:
2024/09/19— CogVideoX-5B-I2V added image-conditioned video generation to the series, alongside text-to-video and video continuation. - 🔥
2024/09/19— CogVLM2-Caption, used to describe video data during training, was released. - 🔥
2024/08/27— CogVideoX-5B was released with inference optimizations intended to make the larger model more accessible. - 🔥
2024/08/06— A 3D Causal VAE and the first CogVideoX-2B model were open-sourced. - 🌱 Earlier work: The original CogVideo text-to-video research introduced a large Transformer-based approach to video generation.
Table of Contents
Jump to a specific section:
Quick Start
Prompt Optimization
CogVideoX was trained with detailed descriptions. A clear, specific prompt can make a meaningful difference to the resulting video; describe the subject, setting, action, lighting, and camera movement before running a model.
SAT
Use Python 3.10 through 3.12 for the documented workflows.
The SAT implementation includes inference and fine-tuning examples for SAT model weights. It is intended as a starting point for researchers adapting the model structure.
Diffusers
Use Python 3.10 through 3.12 for the documented workflows.
pip install -r requirements.txtThe Diffusers inference example explains common generation parameters. Quantized inference using Diffusers and TorchAO can reduce memory requirements, although actual performance depends on the hardware and configuration.
Gallery
CogVideoX-5B
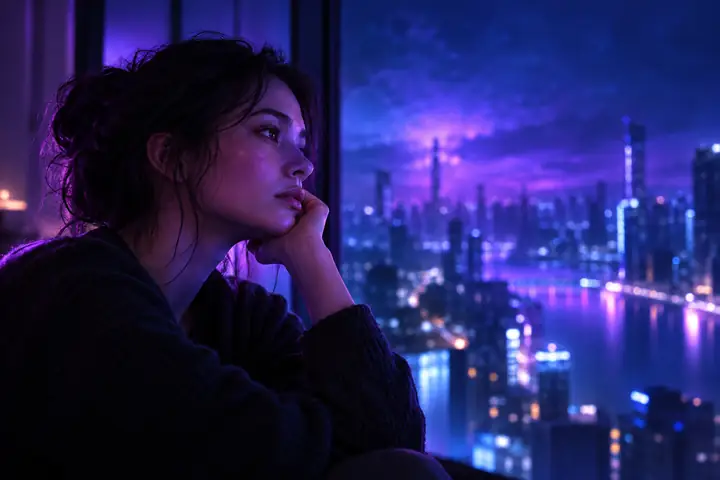
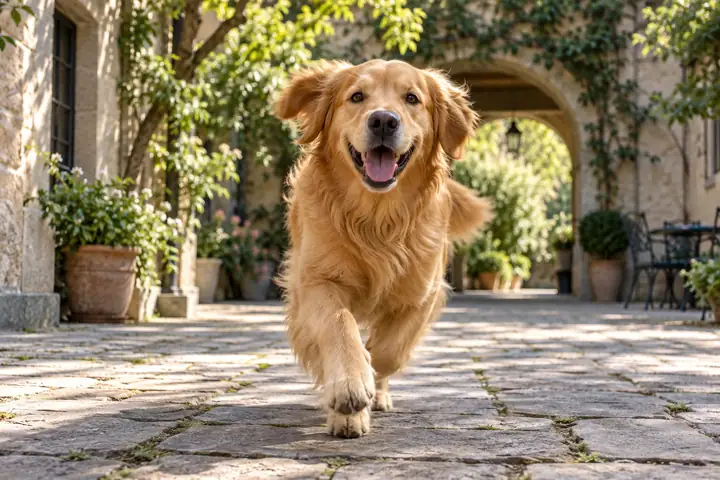
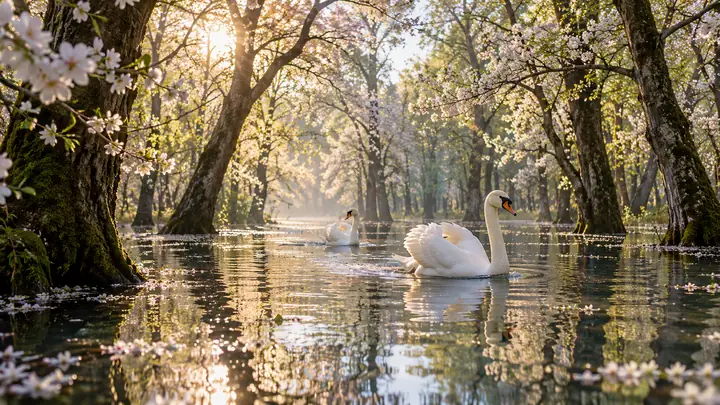
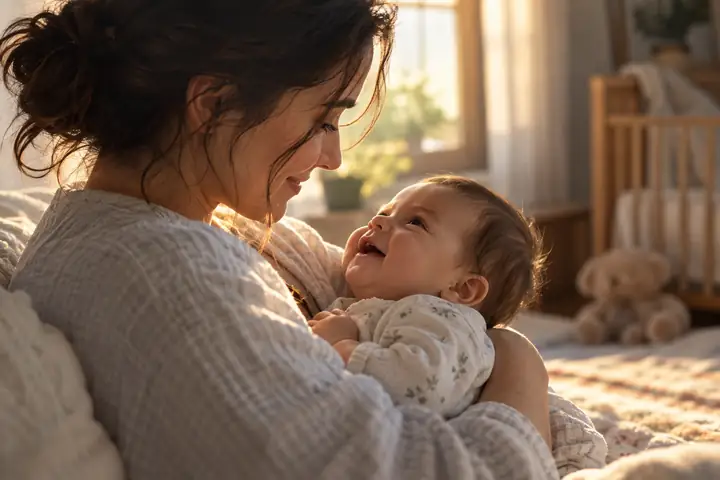
CogVideoX-2B
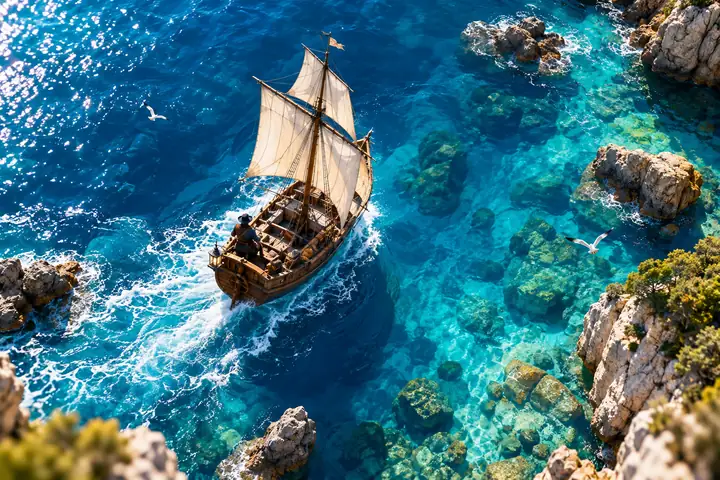
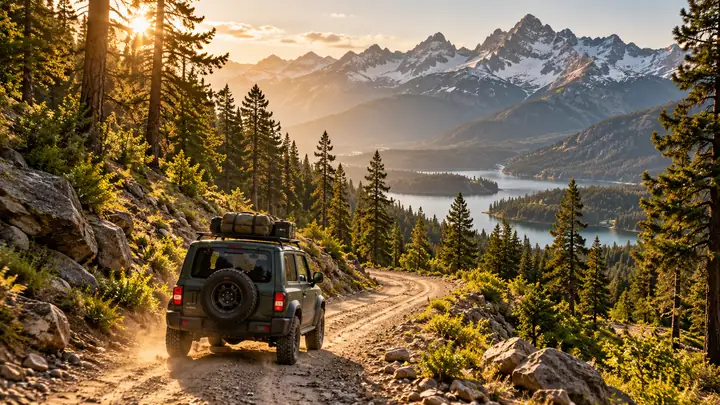
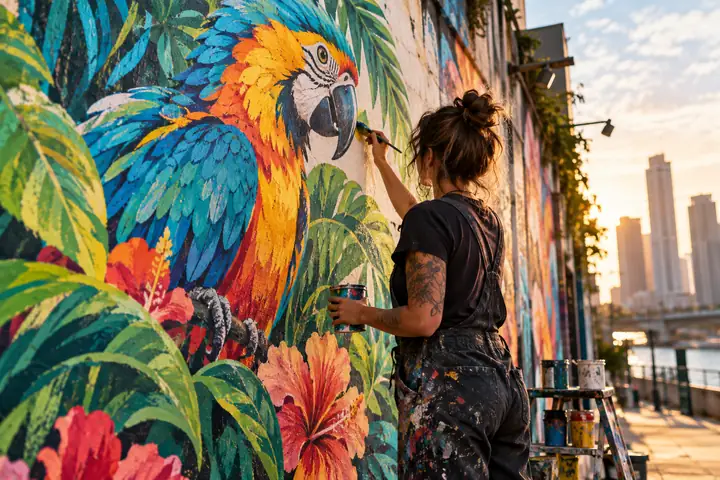
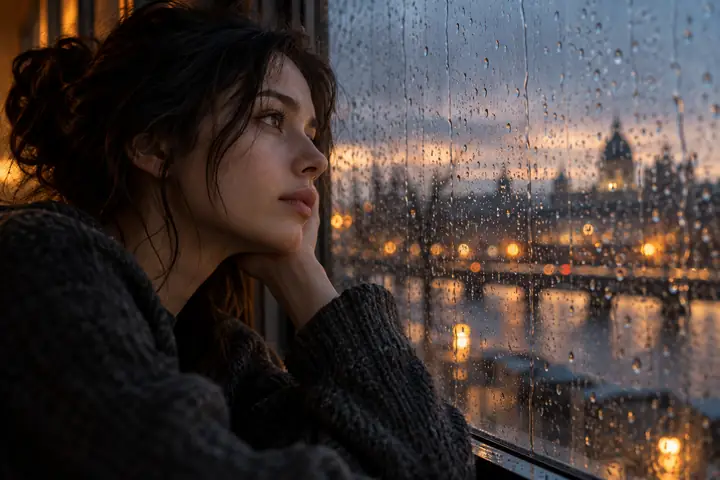
These stills illustrate the kinds of scenes explored in the model gallery.
Model Introduction
CogVideoX is an open-source family of video generation models. The overview below compares the published variants and their basic generation characteristics.
| Model Name | CogVideoX1.5-5B | CogVideoX1.5-5B-I2V | CogVideoX-2B | CogVideoX-5B |
|---|---|---|---|---|
| Release Date | November 8, 2024 | November 8, 2024 | August 6, 2024 | August 27, 2024 |
| Video Resolution | 1360 × 768 | Variable dimensions within the documented limits | 720 × 480 | 720 × 480 |
| Number of Frames | 16N + 1; default 81 | 16N + 1; default 81 | 8N + 1; default 49 | 8N + 1; default 49 |
| Inference Precision | BF16 recommended | BF16 recommended | FP16 recommended | BF16 recommended |
| Single GPU Memory | Depends on implementation and optimizations | Depends on implementation and optimizations | Depends on implementation and optimizations | Depends on implementation and optimizations |
| Multi-GPU Usage | Supported by applicable workflows | Supported by applicable workflows | Workflow-dependent | Workflow-dependent |
| Prompt Language | English | English | English | English |
| Prompt Token Limit | 224 tokens | 224 tokens | 226 tokens | 226 tokens |
| Video Length | 5 or 10 seconds | 5 or 10 seconds | 6 seconds | 6 seconds |
| Frame Rate | 16 frames / second | 16 frames / second | 8 frames / second | 8 frames / second |
| Position Encoding | 3d_rope_pos_embed | 3d_rope_pos_embed | 3d_sincos_pos_embed | 3d_rope_pos_embed |
| Explore Models | Model options | Image-to-video options | Model options | Model options |
Data Explanation
- Published memory figures depend on the implementation, device architecture, precision, and enabled optimizations. They should not be treated as guarantees for every GPU.
- Sequential CPU offload, VAE slicing, and VAE tiling can reduce peak memory use, with a possible speed trade-off.
pipe.enable_sequential_cpu_offload()
pipe.vae.enable_slicing()
pipe.vae.enable_tiling()- Multi-GPU inference requires its own configuration; sequential CPU offload is not used in that arrangement.
- INT8 inference can accommodate lower-memory devices but may run more slowly.
- CogVideoX-2B was trained in FP16; the 5B variants were trained in BF16.
- Quantization tools can reduce the memory needs of the text encoder, transformer, and VAE. Results vary by hardware.
- The documented inference prompts are in English; other-language prompts can be translated before use.
Friendly Links
Community projects have explored acceleration, longer video, alternative interfaces, deployment, and fine-tuning around CogVideoX. Here is a sampling of the kinds of work in that ecosystem:
- LeMiCa: cache-based diffusion inference acceleration.
- RIFLEx-CogVideoX: techniques for extending generated video length.
- CogVideoX-Fun: a pipeline supporting flexible resolutions and launch methods.
- CogStudio: a separate Gradio-style web interface.
- Xorbits Inference: distributed model deployment workflows.
- ComfyUI-CogVideoXWrapper: integration into a node-based workflow.
- VideoSys: infrastructure for video generation pipelines.
- AutoDL Space: a community deployment example.
- Interior Design Fine-Tuning Model: a domain-specific fine-tuned variant.
- xDiT: scalable inference across multiple GPUs.
- CogVideoX-Interpolation: keyframe interpolation experiments.
- DiffSynth-Studio: a diffusion workflow engine.
- CogVideoX-Controlnet: a control-focused community module.
- VideoTuna: a collection of video generation model workflows.
- ConsisID: research into identity consistency in generated video.
- Step-by-step tutorials: installation and optimization walkthroughs.
Project Structure
The open-source project organizes basic usage, inference, model conversion, and fine-tuning examples for the CogVideoX model family.
Quick Start with Colab
The example notebooks cover several starting points:
- CogVideoX-5B text-to-video generation.
- Quantized text-to-video inference.
- CogVideoX-5B image-to-video generation.
- CogVideoX-5B video-to-video workflows.
Inference
- CLI demo: common generation parameters and a command-line inference example.
- Quantization demo: lower-memory model inference configuration.
- VAE demo: running the video autoencoder separately.
- Space demo: an interface with optional frame interpolation and super-resolution workflows.

- Prompt conversion: expanding short user input into longer descriptions suited to the model.
- Web demo: a simple browser interface for exploring video generation.
finetune
- Fine-tuning examples describe the Diffusers-based CogVideoX workflow.
sat
- The SAT folder contains model-weight inference and fine-tuning examples for researchers.
Tools
Supporting tools cover model conversion, captioning, adapter handling, and parallel inference.
- SAT-to-Diffusers model-weight conversion.
- Video caption generation.
- Exporting and loading fine-tuned LoRA adapters.
- Prompt-assisted generation experiments.
- Parallel inference across multiple GPUs.
CogVideo (ICLR ’23)
The earlier CogVideo research investigated large-scale Transformer pretraining for text-to-video generation.
CogVideo demonstrated relatively high-frame-rate video generation. A four-second, 32-frame example is represented below.


These examples illustrate the earlier text-to-video research. The original example prompts were written in Chinese.
Citation
If the research is useful to your work, cite the relevant CogVideoX or CogVideo paper.
@article{yang2024cogvideox,
  title={CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer},
  author={Yang, Zhuoyi and others},
  journal={arXiv preprint arXiv:2408.06072},
  year={2024}
}

@article{hong2022cogvideo,
  title={CogVideo: Large-scale Pretraining for Text-to-Video Generation via Transformers},
  author={Hong, Wenyi and others},
  journal={arXiv preprint arXiv:2205.15868},
  year={2022}
}
Model-License
The repository code and CogVideoX-2B model are published under Apache 2.0 licensing. CogVideoX-5B model weights, including text-to-video and image-to-video variants, have a separate model license. Review the applicable terms before using model weights.